Self-Service Software Training Models for Customer Success Teams
Self-service training cuts CS costs while boosting customer engagement and reducing churn.
Picture a CS manager opening the calendar on a Monday morning and finding the same onboarding call booked for the fifteenth time that month, same slides, same screen share, same questions about where to find the export button. That moment is where the live-touch training model starts to break. It breaks structurally, not because anyone on the team is slow or unprepared, the moment a CS team's account load outpaces the hours available for individual calls and onboarding sessions. CSMs are already carrying too many accounts per representative, and every new customer folded into a live-training model adds a fixed time cost that compounds month over month. The math does not bend: more accounts means more hours, and hours do not scale the way customer counts do.
The cost gap between self-service and assisted support is structural. Self-service channels cost a fraction of what assisted support costs per contact, and that difference makes the economic case for self-service training unavoidable once a CS team crosses a certain account volume. But the cost argument is only half of it. Customers who do not get structured early education disengage. They file more support tickets, adopt fewer features, and churn at higher rates. The training gap appears in the renewal forecast as much as in the CS team's calendar.
Self-Service Training vs. a Folder of Recordings
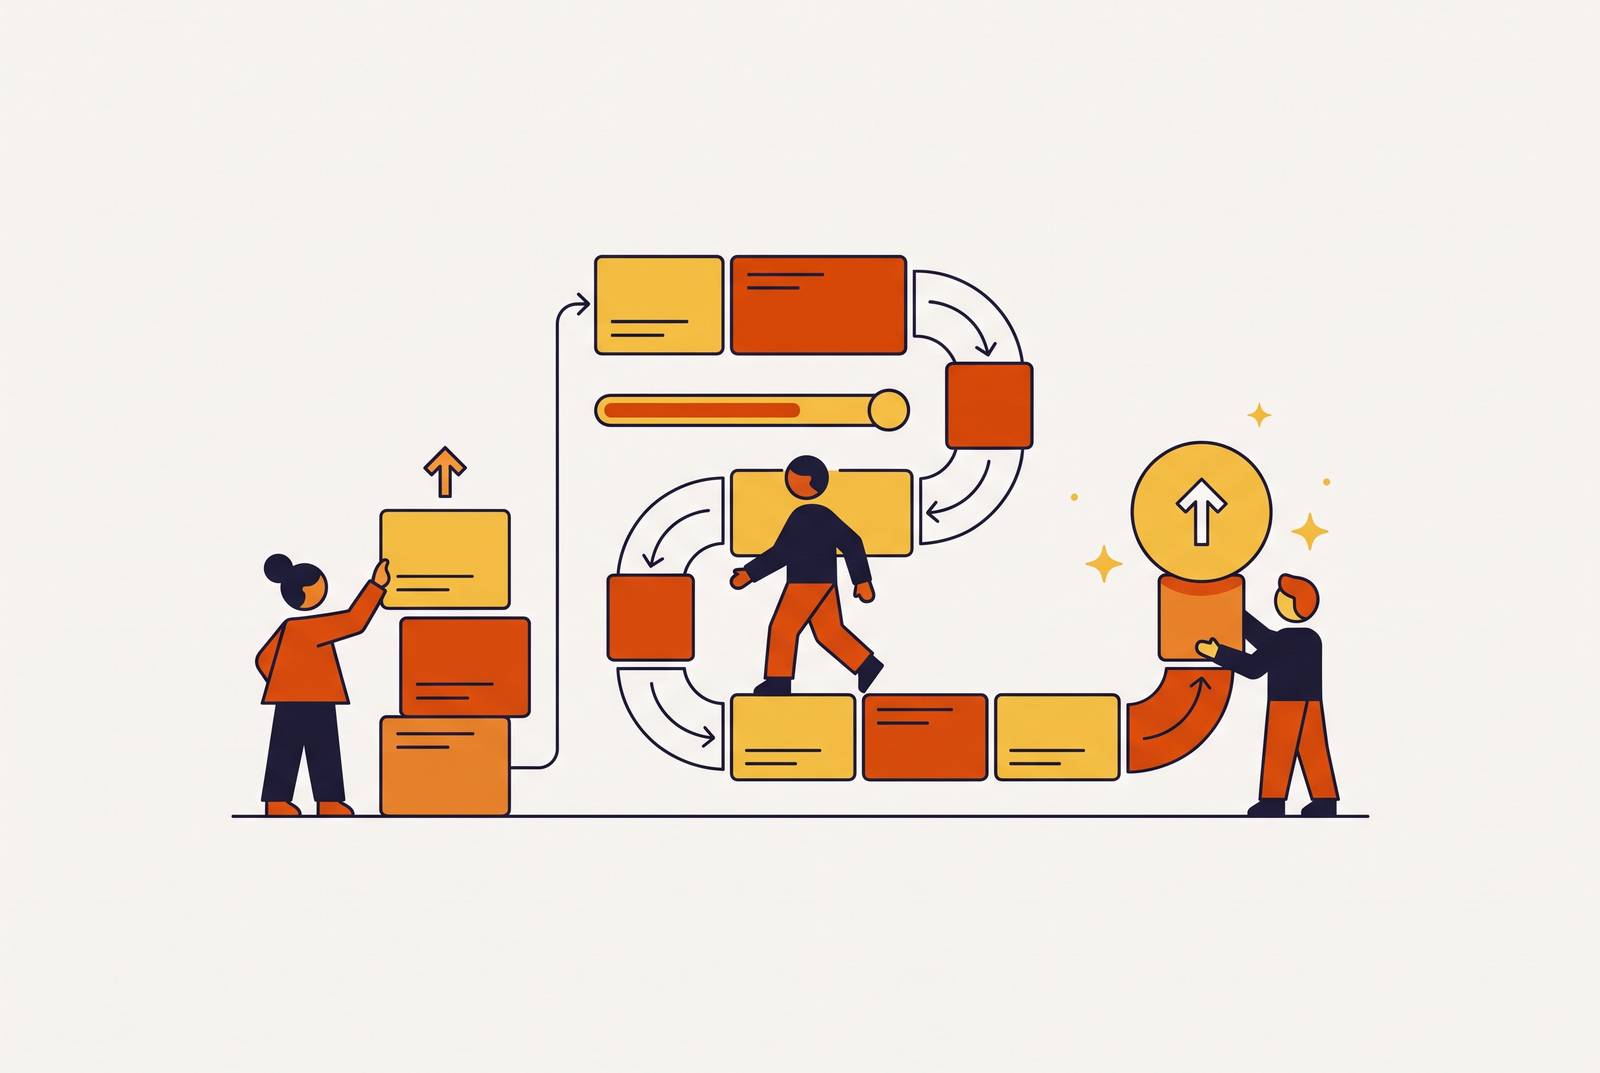
A self-service training program is a structured, one-to-many education system built with deliberate architecture. An ad-hoc library of screen recordings, however large, lacks that architecture, no matter how many videos get added to the shared drive. The difference has nothing to do with volume of content. A real program maps the customer journey, assigns specific content to specific stages, and creates coherent paths a customer can follow.
Three categories of customer education software serve distinct functions, and most mature programs combine them: LMS platforms handle structured, course-based learning; digital adoption platforms deliver in-app contextual guidance; virtual labs give customers hands-on practice in a safe environment. So a self-service model picks the right layer for each learning need. That same logic applies to the customers themselves. A first-time user, a power user, and an account admin need different learning paths built for their specific context, not the same flat library with a search bar bolted on top.
Content architecture carries as much weight as content quality. Modular, role-aligned paths with branching options let a customer find the exact thing they need at the moment they need it, which outperforms a flat dump of videos sorted by upload date. Building that architecture means answering four design questions in sequence: how the curriculum maps to the customer journey, how the content gets produced without draining the team, where it gets delivered, and how anyone knows it's working. Those four questions set the order for everything that follows.
Designing the curriculum: mapping content to the customer journey before producing anything
The biggest source of wasted production effort in customer training is building content before anyone decides what the customer needs to know, when they need to know it, and in what sequence. Teams that start with a feature list end up with a library organized around the product's menu structure.
A better starting point is four journey stages, each with its own content demands. Onboarding content exists to get the customer to first value as fast as possible. Adoption content expands usage once that first value has landed. Advanced content serves power users who already know the basics and want depth. Renewal content reinforces ROI, reminding the customer why the investment paid off. Each stage assumes a different level of prior knowledge, and content written for one stage rarely transfers cleanly to another.
Microlearning is the dominant format for self-service training because it matches the actual moment of need. A customer trying to complete a task right now wants a short, focused module, not a long course they'll abandon halfway through. Research on microlearning segment length varies on the exact number, but the practical rule holds regardless: keep each piece short, and if a topic genuinely needs more time, break it into multiple modules.
The sharpest curriculum-design habit is mapping each content piece to a specific behavior change. "Customer can complete their first export without contacting support" is a better module goal than "export functionality overview," because the first version gives production a clear finish line and gives measurement something concrete to check later.
Producing training content at scale without a video production team
For years, the cost of professional training video was the main reason most self-service libraries stayed small, stayed outdated, and stayed limited to a single language. Traditional production ran $1,000 to $5,000 per finished minute, a price that kept most CS teams updating their libraries rarely. AI-assisted production workflows have removed that constraint, compressing both the cost and the timeline so a job that once took a multi-day shoot now takes a few hours.
A repeatable production workflow for software training looks like this: record the screen, clean up the script with AI assistance, add a lifelike voiceover, apply smart zoom and captions, export in a format ready for the LMS, and keep a fast path open for updates when the product changes. That last step matters because most self-service libraries don't die from lack of initial content, they die slowly as updates lag behind. They die slowly, as the software changes, the recordings drift out of accuracy, and nobody has the time to reshoot. A production workflow built for fast updates, meaning template-driven, AI-assisted, and modular, is the only approach that keeps a library accurate over time.
One efficiency gets missed constantly: video and documentation should come out of the same workflow. A screen recording captured once can become a finished video and a step-by-step how-to article or SOP, doubling the content surface area without doubling the production time behind it.
Choosing the delivery infrastructure: LMS, in-app guidance, or both
Deciding where training content lives depends on one question: does the customer need to understand a concept before using the product, or do they need help at the exact moment they're trying to do something inside it? Those two needs call for different infrastructure, and most mature programs end up using both.
LMS platforms fit structured programs, certification tracks, and content customers work through before or between product sessions. A few options illustrate the range available. Docebo is an AI-driven customer education platform built for enterprise scale and monetized training programs, priced on a custom basis. TalentLMS deploys fast and fits a tighter budget, and its entry-level annual plans cover a small user base. 360Learning runs on a collaborative, peer-learning model, priced per user monthly up to a defined cap on its team plan. Trainn focuses on video-based customer onboarding and training, available through annual team plans or monthly individual plans for a small seat count.
Digital adoption platforms serve a different purpose entirely: in-the-moment, contextual guidance delivered through onboarding checklists, tooltips, and product tours that teach customers inside the product itself, without a separate login. DAPs complement LMS platforms. Many organizations run both at once, letting the LMS handle formal certification and deep skill-building while the DAP handles the procedural "how do I do this right now" moments that come up mid-task.
One access distinction separates customer-facing platforms from internal ones. Customer-facing LMS platforms need self-serve access with no login required, along with white-label branding, features that internal employee LMS platforms tend to treat as secondary. Teams serving multilingual audiences face a related technical requirement: delivery infrastructure needs to generate per-language SCORM or xAPI packages that track completion and assessment data independently for each language. A single multilingual package without that per-language separation can run into uneven LMS support and tracking problems, which makes per-language packaging the safer default for reliable reporting.
Localization as a structural decision, not a late-stage project
CS teams that treat localization as something handled after the primary-language content ships will always run behind, with a permanent lag between the primary-language library and every other audience it needs to reach. The structural fix is building localization into the same workflow that produces the original content, so translating a module becomes close to a single step.
Traditional studio dubbing made large-scale multilingual training financially out of reach for most CS teams. AI-based localization changes that math directly, delivering up to 80% cost savings compared to traditional studio dubbing and cutting turnaround from weeks down to hours or days. That shift turns localization from a quarterly initiative into a routine step attached to every new module.
The parity principle makes the structural point clearest: adding a new target language should require no additional production infrastructure. The same platform workflow should handle three languages or thirty at roughly the same cost per minute. For teams running an LMS, the technical constraint carries over from the delivery discussion: localization needs to produce per-language SCORM packaging, because a single multilingual file without independent tracking per language can't meet the reporting standards most enterprise LMS deployments require.
Measuring whether the self-service model is working
Most CS teams measure training at the wrong layer. Completion rates and other activity metrics feel like proof that the program works, but the actual business case lives one or two layers deeper, in the behavioral and strategic metrics that connect training to retention, adoption, and revenue.
A three-layer framework keeps that distinction clear. Activity metrics, things like course starts, completion rates, and content consumption, establish basic operational visibility, but they don't prove business impact by themselves. Behavioral metrics go further: feature adoption rate, certification achievement, and support ticket volume for trained versus untrained cohorts show where the education is actually landing inside the product. Strategic metrics make the case to leadership directly, through net revenue retention, time-to-value, churn and retention lift, support deflection, and expansion velocity. Connecting completion data to outcomes like retention is what makes the investment defensible. A platform that tracks only course-level completion, with no link to CRM or customer success data, leaves a CS team unable to draw that connection no matter how good the content is.
Attribution deserves honest treatment, since the voluntary-completion bias described next can otherwise be papered over with a convenient comparison. Customers who voluntarily complete training are often already more engaged than customers who don't, which inflates any simple comparison between the two groups. A more defensible method anchors on a specific exposure event, such as completing an onboarding path or earning a certification within a defined window, and then runs trained and untrained cohorts in parallel from that point forward. That approach doesn't erase the bias entirely, but it gives CS leaders a comparison they can defend in front of a leadership team that will ask hard questions about causation.
The strongest version of this argument reframes training as a growth lever. Expansion velocity, how fast trained customers move into new usage, new seats, or new product lines, ties training directly to revenue growth, not just to deflected support tickets.
Keeping the self-service library current as the product changes
If nobody actively maintains a self-service training library, it turns into a liability. Customers who follow outdated instructions lose trust in the content and, by extension, in the product itself.
Software's constant release cycles force a continual stream of content updates. Products change on release cycles that rarely pause to accommodate the training team's schedule, and a library built without a fast update path will fall behind within months of launch. The design principle that prevents this is modularity: content built in short, discrete segments is far easier to update than long-form recordings, because a UI change affecting one step means updating one module, not re-recording a 20-minute walkthrough from scratch.
Template-driven, AI-assisted production workflows keep updates fast enough to match product release schedules. When the UI changes, a team member re-records the single affected segment, AI handles the script and voiceover cleanup, and the updated module replaces the old one without touching anything else in the surrounding path. That speed only works if someone is responsible for triggering it. Every training module needs a named owner who reviews it after major product releases, because without clear ownership, nothing gets updated until a customer complains about it directly.
The last piece of the maintenance system is a recurring audit built into the CS team's regular operating rhythm. A quarterly review of completion rates alongside support ticket topics shows which modules customers are actually using, which ones they're skipping, and which ones are generating follow-up questions that point to a real gap in the content. That cadence turns maintenance into a scheduled part of the job instead of a crisis that only gets attention once the library has already fallen out of date.